Extract embedded subtitles
Most sources carry an embedded text track. Pick "extract subtitles" and you get an SRT with the original text in seconds, fully offline.
SRT · no network · original text
Avoxkit · Subtitles · On-device ASR
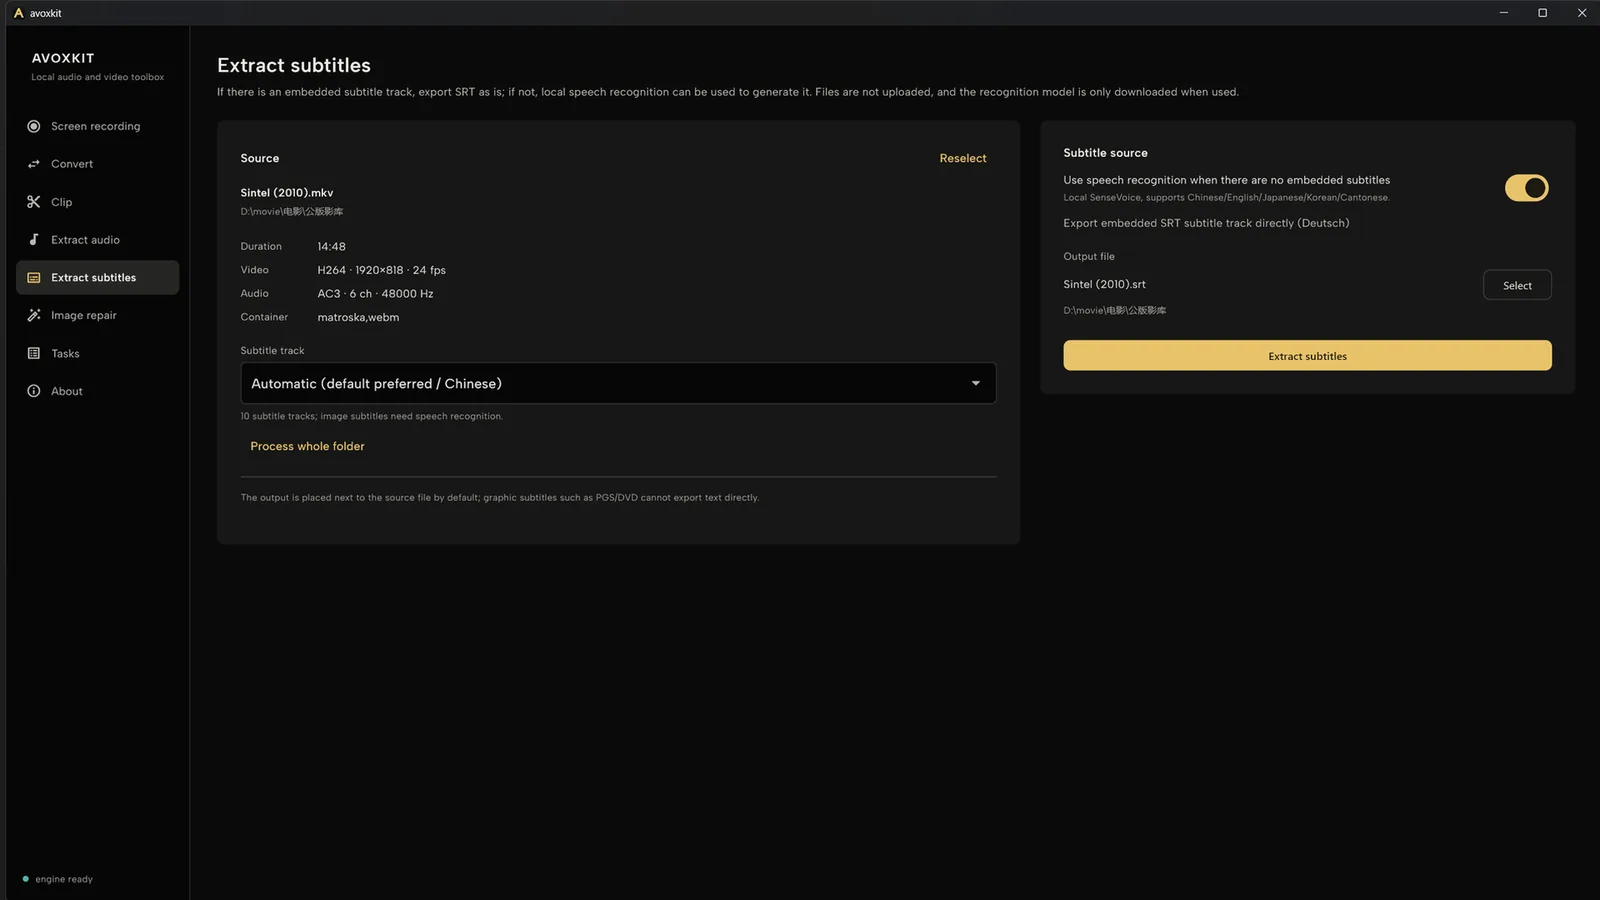
If the video already has an embedded text track, export it as SRT directly. If it doesn't, generate subtitles with on-device speech recognition. Nothing is uploaded, there is no queue to wait in, and no membership to pay for.
Two paths
Subtitle work in Avoxkit follows one rule: extract the embedded track when it exists, recognize when it doesn't.
Most sources carry an embedded text track. Pick "extract subtitles" and you get an SRT with the original text in seconds, fully offline.
SRT · no network · original text
Material without a text track — phone footage, screen recordings, dictated audio — runs through on-device recognition in Chinese, English, Japanese, Korean and Cantonese. The model (~230 MB, SHA-256 checked) downloads on first use, then works offline.
SenseVoice · single files and folder batches
Batch
Drop in a folder, and everything lines up in one queue with shared progress and one-click retry for failed items. While a job runs you can watch the picture or the audio envelope.
Output goes to a temp file first; the final file is replaced only on success.
Limits
Recognition is not a transcript.Names and homophones can come out wrong; proofread subtitles before publishing.
Recognition takes machine time.Long videos run locally and take as long as your CPU allows — not the minutes-only promise of a cloud service.
Accuracy depends on audio.Accents, background noise and multiple speakers hurt results; Mandarin and English are the most robust.
Model downloads on demand.About 230 MB, model files only; it never reads your media and doesn't download until used.
Get
Current release 0.2.0 for Windows 64-bit and macOS (Apple Silicon), entirely free.
Download from GitHub Releases, or see the Avoxkit home page.
No. Both extraction and recognition run on this machine; the app has no telemetry or auto-upload logic and needs no account.
Recognition covers Chinese, English, Japanese, Korean and Cantonese. Embedded track extraction is language-independent — what the track says is what you get.
It depends on the machine; a normal desktop is usually in the minutes range. Batches queue up and run unattended.
The output is standard SRT, editable in any text editor. For ASS/VTT conversion or time shifting, use the free browser tools in the media toolkit.